Scrape Cruise Data Distribution Report US — Update Frequency, Incremental Data Delivery, Licensing Models and Integration Strategies
Introduction
The U.S. cruise industry operates across a complex digital ecosystem where cruise lines, travel agencies, online travel platforms, aggregators, wholesalers, and technology companies continuously exchange information about itineraries, ships, cabins, fares, availability, ports, sailing schedules, promotions, and onboard offerings. As this information changes frequently, businesses increasingly require structured datasets rather than manually collected website information.
Scrape Cruise Data Distribution Report US to understand how cruise-related information can be collected, standardized, refreshed, and distributed for commercial intelligence. A well-designed data pipeline can combine itinerary information, departure dates, destination ports, cabin categories, pricing, occupancy indicators, promotions, and availability into a consistent analytical dataset.
Cruise Data Scraping can support competitive monitoring by transforming fragmented cruise information into structured records suitable for dashboards, pricing engines, market research, and travel applications.
Cruise Data Update Frequency Intelligence US is particularly important because cruise prices and availability can change as departure dates approach. Monitoring daily, hourly, or event-driven changes enables businesses to distinguish stable market characteristics from short-lived pricing movements.
The following report examines the data architecture, commercial applications, delivery models, and analytical opportunities associated with U.S. cruise data distribution. The numerical examples in the tables are illustrative benchmark figures designed to demonstrate how a cruise-data intelligence program can be structured; they are not claims of live market measurements.
Mapping the U.S. Cruise Data Ecosystem
Cruise data distribution begins with the identification of relevant sources and the extraction of structured information. Depending on business objectives, a collection system may monitor cruise-line websites, travel marketplaces, booking platforms, agency portals, destination pages, and other publicly accessible digital sources.
A mature dataset normally contains fields such as cruise line, vessel, itinerary name, departure port, destination, sailing date, duration, cabin category, base fare, taxes, promotional discount, availability status, occupancy indicator, currency, timestamp, and source URL.
The value of the dataset increases substantially when records are normalized. For example, one platform may describe a cabin as "Balcony," another as "Veranda," and another as "Oceanview Balcony." A standardized taxonomy makes these records comparable.
Geographic normalization is equally important. A cruise departing from Miami may visit Nassau, Cozumel, Grand Cayman, and other destinations, while another sailing from Los Angeles may focus on Mexico or the Pacific Coast. Converting port names into standardized identifiers, countries, regions, and coordinates allows route-level analysis.
Building a Reliable Data Collection Framework
An effective cruise scraping architecture generally follows a multi-stage process. Source discovery identifies relevant pages and data endpoints. Extraction retrieves visible and structured information. Validation checks whether essential fields are complete. Normalization standardizes names, currencies, dates, cabin categories, and destinations.
The next stage is deduplication. The same sailing can appear across multiple websites with slightly different descriptions or prices. A composite identifier based on cruise line, vessel, departure date, itinerary, and duration can help identify duplicate records.
Timestamping is another critical component. A price without a timestamp has limited analytical value because cruise fares are dynamic. Historical snapshots allow analysts to reconstruct how prices changed over time.
For large-scale operations, distributed scraping infrastructure can divide collection workloads by cruise line, destination, sailing date, or website. Proxy management, request scheduling, browser automation, error handling, and source-specific parsers can be incorporated where technically and legally appropriate.
Measuring Fare Movements and Competitive Positioning
Cruise Pricing Intelligence transforms raw fare observations into commercially useful indicators. Instead of viewing a cruise price as an isolated number, businesses can analyze it against sailing date, cabin category, itinerary duration, departure port, season, promotional status, and competing offerings.
For example, a pricing dashboard could calculate the median fare for comparable seven-night Caribbean sailings. Another metric could measure the difference between an early observation and the latest observed price.
Price-per-night analysis is particularly useful because cruises have different durations. A $1,400 seven-night itinerary and a $1,100 five-night itinerary should not be evaluated solely on total price. Normalizing fares by passenger, cabin, and night creates a more meaningful comparison.
Taxes and fees should also be separated from base fares wherever the source makes this distinction available. Otherwise, apparent pricing advantages may simply reflect different fee presentation methods.
Illustrative U.S. Cruise Data Distribution Benchmark
| Data Category | Example Records/Month | Update Frequency | Average Fields/Record | Historical Retention | Primary Intelligence Use | Example Change Rate | Delivery Format |
|---|---|---|---|---|---|---|---|
| Cruise Listings | 48,000 | Daily | 28 | 24 months | Market coverage | 4.8% | JSON/CSV |
| Sailing Schedules | 32,500 | Daily | 24 | 36 months | Route planning | 2.6% | JSON/Parquet |
| Cabin Prices | 185,000 | 6-hourly | 36 | 18 months | Price monitoring | 18.7% | API/JSON |
| Cabin Availability | 142,000 | Hourly | 31 | 12 months | Inventory intelligence | 23.4% | API |
| Promotions | 26,400 | 6-hourly | 22 | 18 months | Offer tracking | 14.2% | CSV/JSON |
| Port Calls | 41,800 | Daily | 19 | 36 months | Destination analysis | 1.9% | CSV |
| Ship Profiles | 1,250 | Weekly | 34 | 60 months | Fleet intelligence | 0.7% | JSON |
| Itineraries | 17,600 | Daily | 29 | 36 months | Route comparison | 3.8% | API |
| Taxes & Fees | 91,000 | 6-hourly | 17 | 18 months | Total-price analysis | 8.6% | JSON |
| Review Signals | 75,000 | Daily | 15 | 24 months | Experience analysis | 5.4% | CSV |
| Departure Ports | 650 | Weekly | 16 | 60 months | Geographic analysis | 0.4% | JSON |
| Destination Ports | 4,800 | Weekly | 18 | 60 months | Destination intelligence | 0.8% | JSON |
The benchmark demonstrates why cruise intelligence requires more than a single price field. High-frequency pricing and availability records may require hourly or six-hourly collection, whereas ship profiles and port metadata can often be refreshed much less frequently.
Structuring Commercial Data Access and Usage
Cruise Licensing models data Extraction US can support businesses that need structured cruise information for internal analytics, commercial applications, or customer-facing platforms. Different data programs may use one-time datasets, recurring feeds, APIs, or customized enterprise arrangements depending on the required freshness and permitted usage.
A one-time historical dataset may be appropriate for academic research or market modeling. Scheduled datasets can support recurring analytics, while API-based distribution is better suited to applications that require near-real-time access.
Data licensing should be considered separately from technical extraction. Businesses should verify source terms, permissions, contractual restrictions, copyright considerations, and applicable platform policies before collecting or redistributing information.
Connecting Structured Cruise Data With Applications
Real-Time Cruise Data API Integration US enables downstream applications to access structured cruise information without repeatedly processing raw web pages. An API layer can expose normalized endpoints for cruise lines, vessels, itineraries, sailings, ports, fares, cabins, promotions, and availability.
For example, an application might request all Caribbean cruises departing within the next 90 days. Another system could retrieve only balcony cabins whose prices changed during the previous six hours.
API integration also creates opportunities for event-driven intelligence. When a monitored fare changes beyond a predefined threshold, a downstream system can generate an alert, update a dashboard, or initiate another analytical workflow.
Establishing Recurring Data Delivery
Scheduled Dataset Delivery provides a practical alternative for organizations that do not require continuous API access. Data can be delivered at predefined intervals such as daily, weekly, or multiple times per day.
A daily file might contain complete U.S. cruise coverage, while smaller incremental files contain only records that changed since the previous delivery. This reduces bandwidth, processing requirements, and storage duplication.
Delivery can be organized around JSON, CSV, Excel, Parquet, database tables, cloud storage, SFTP, or other approved enterprise mechanisms. Metadata should accompany each delivery, identifying extraction time, schema version, record count, and update status.
Reducing Data Transfer Through Incremental Updates
US Cruise Incremental Dataset Delivery is especially valuable for large datasets. Instead of transmitting hundreds of thousands of unchanged records, the pipeline can identify newly created, modified, removed, or unavailable records.
Suppose a cruise database contains 500,000 historical records but only 18,000 records changed during a particular collection cycle. Delivering those 18,000 records can substantially reduce downstream processing.
Incremental datasets should ideally include stable record IDs, timestamps, change types, previous values where appropriate, and source identifiers. This enables customers to merge updates into their own databases without reconstructing the entire dataset.
Designing a Responsive Distribution Infrastructure
Real-Time US Cruise Data Distribution supports businesses that need frequent visibility into pricing and inventory. The architecture can combine scheduled crawls with targeted high-frequency monitoring.
A hybrid approach is often more efficient than continuously collecting every field. Stable metadata such as vessel specifications can be updated weekly, itinerary information daily, and price or availability fields hourly or more frequently depending on operational requirements.
Custom Scraping Pipelines can then be designed around individual business requirements. A travel marketplace may prioritize fares and availability, while an investment research company may emphasize capacity, routes, fleet deployment, and historical pricing.
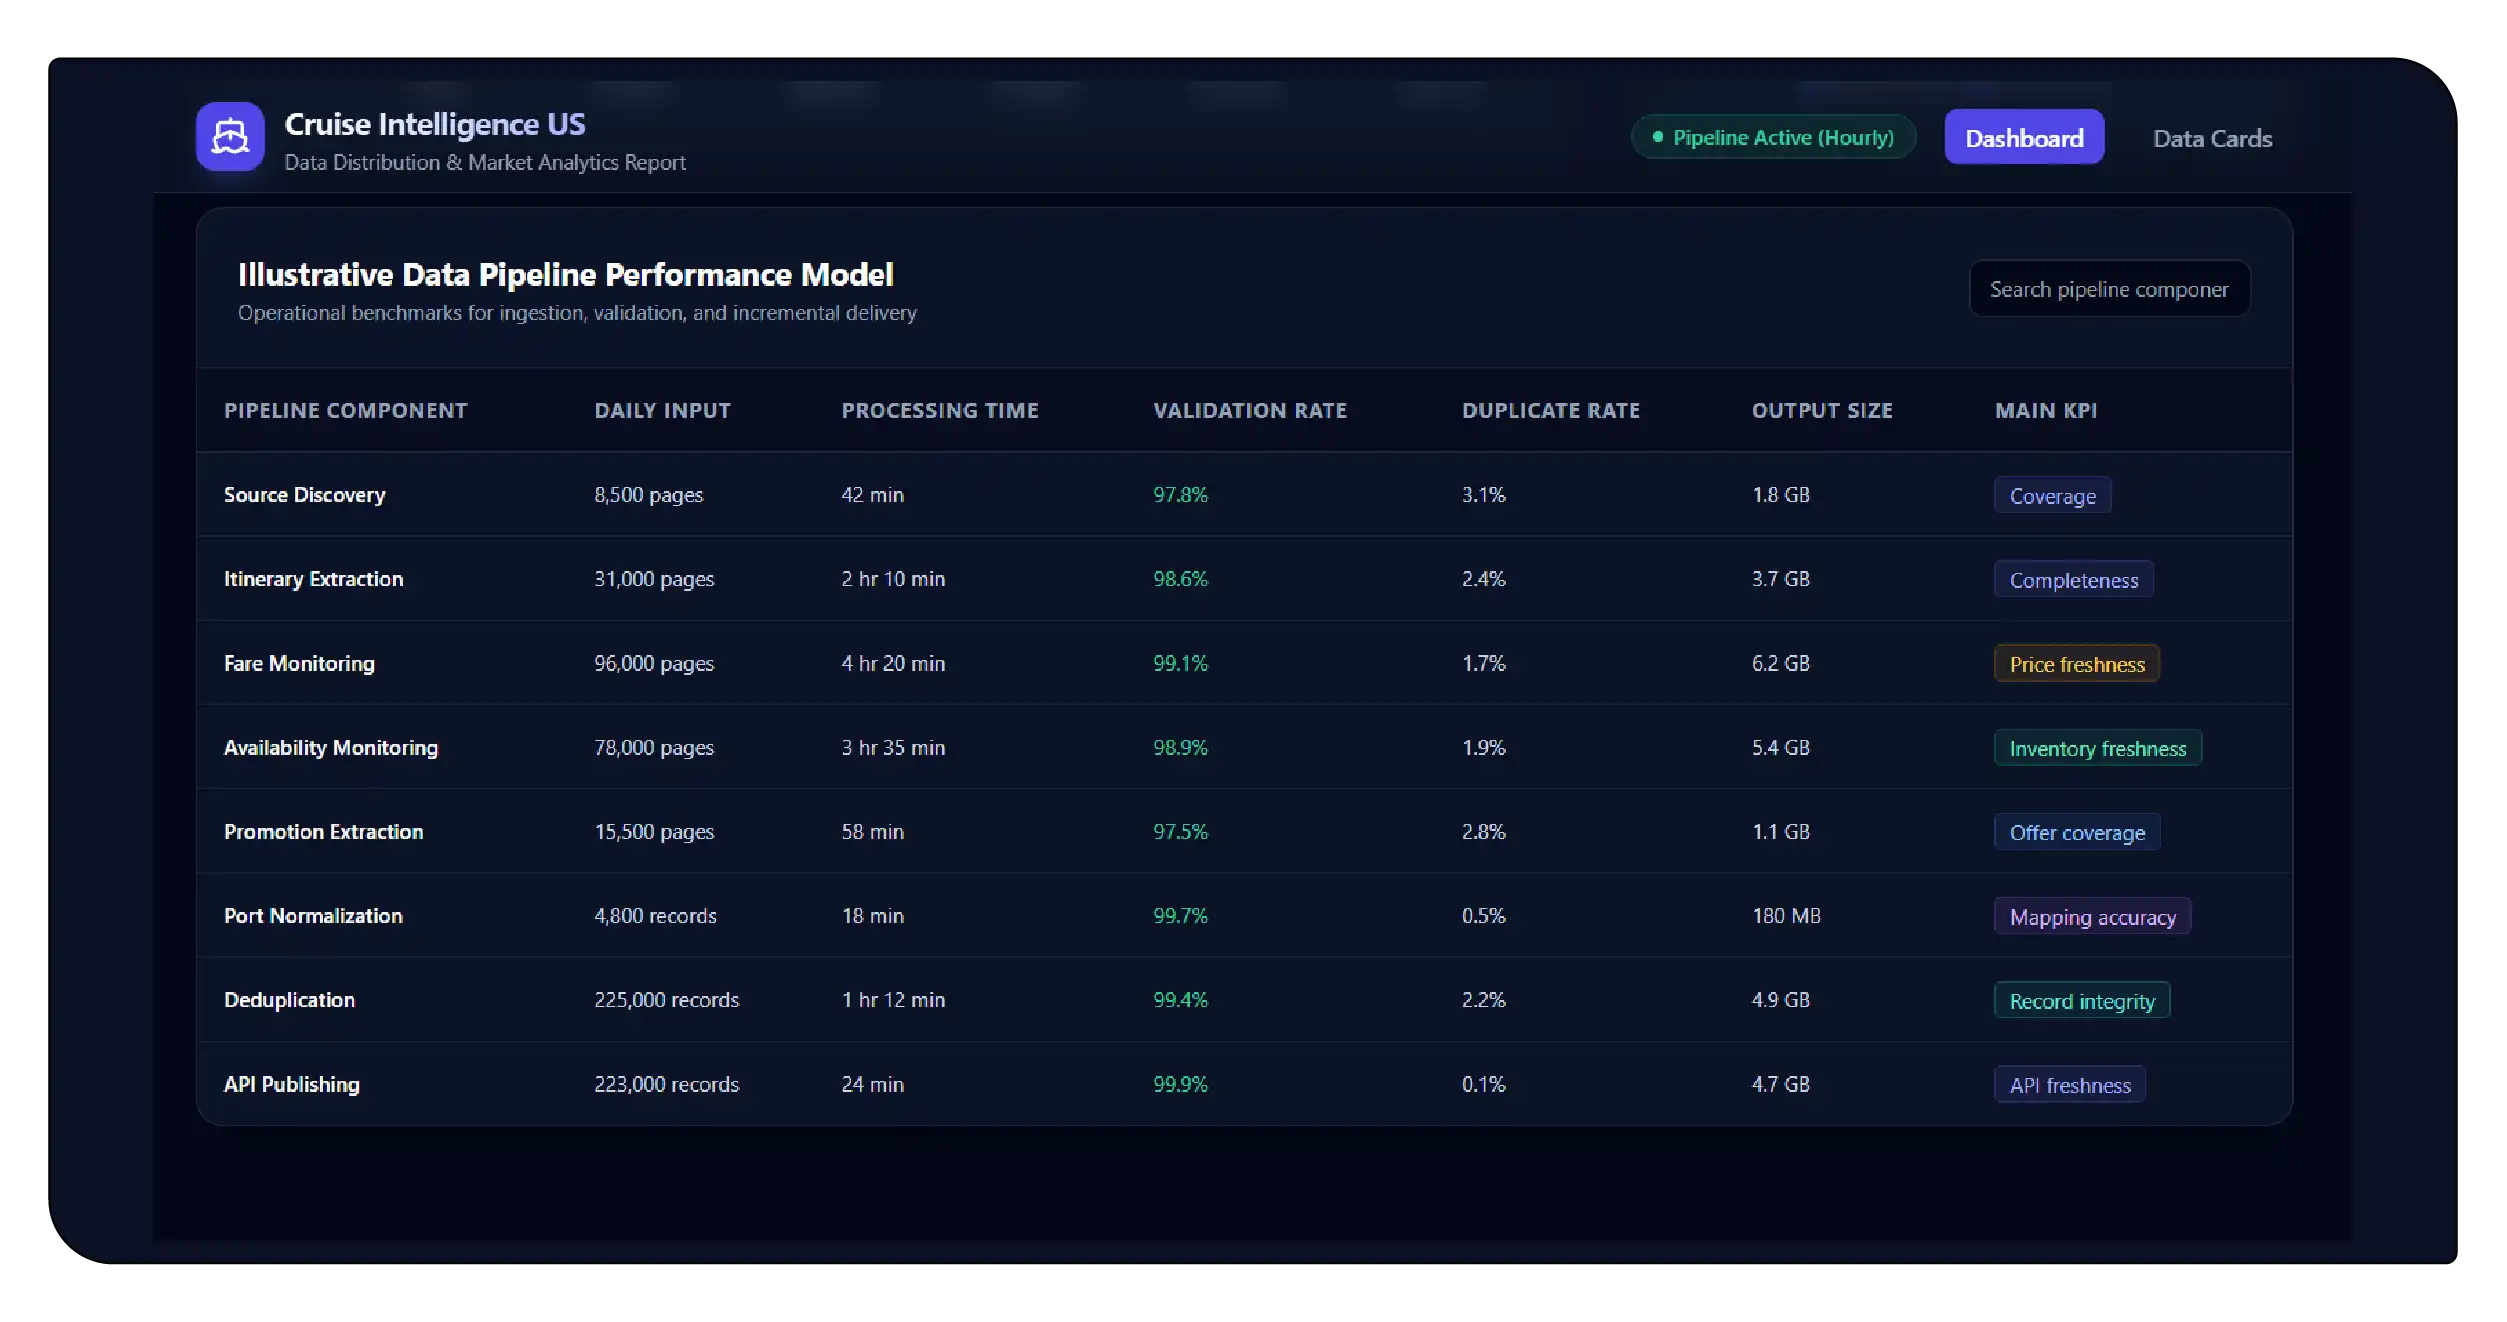
Illustrative Data Pipeline Performance Model
| Pipeline Component | Daily Input | Processing Time | Validation Rate | Duplicate Rate | Incremental Records | Output Size | Refresh Target | Main KPI |
|---|---|---|---|---|---|---|---|---|
| Source Discovery | 8,500 pages | 42 min | 97.8% | 3.1% | 8,200 | 1.8 GB | Daily | Coverage |
| Itinerary Extraction | 31,000 pages | 2 hr 10 min | 98.6% | 2.4% | 29,700 | 3.7 GB | Daily | Completeness |
| Fare Monitoring | 96,000 pages | 4 hr 20 min | 99.1% | 1.7% | 17,800 | 6.2 GB | 6-hourly | Price freshness |
| Availability Monitoring | 78,000 pages | 3 hr 35 min | 98.9% | 1.9% | 21,400 | 5.4 GB | Hourly | Inventory freshness |
| Promotion Extraction | 15,500 pages | 58 min | 97.5% | 2.8% | 4,900 | 1.1 GB | 6-hourly | Offer coverage |
| Port Normalization | 4,800 records | 18 min | 99.7% | 0.5% | 320 | 180 MB | Weekly | Mapping accuracy |
| Deduplication | 225,000 records | 1 hr 12 min | 99.4% | 2.2% | 220,000 | 4.9 GB | Every cycle | Record integrity |
| Quality Validation | 225,000 records | 46 min | 99.2% | 0.8% | 223,000 | 4.8 GB | Every cycle | Data quality |
| API Publishing | 223,000 records | 24 min | 99.9% | 0.1% | 18,000 | 4.7 GB | Continuous | API freshness |
| Customer Delivery | 18,000 changes | 11 min | 99.8% | 0.2% | 18,000 | 410 MB | Scheduled | Delivery success |
These figures illustrate how different components can have different operational priorities. Price monitoring may require significantly greater processing capacity than relatively stable vessel metadata.
Supporting High-Frequency Market Monitoring
Real-Time Cruise Data Distribution Scraping US can combine monitoring, extraction, normalization, validation, and distribution into a unified workflow. The objective is not simply to collect more information but to produce timely and trustworthy information that downstream systems can immediately use.
A robust implementation can assign every observation a timestamp and source identifier. Changes can then be detected by comparing the latest observation with the previous valid record. Significant fare movements can be flagged, while unchanged records can be excluded from incremental delivery.
Machine-readable schemas further improve interoperability. Consistent field naming, controlled vocabularies, standardized date formats, currency normalization, and unique identifiers allow customers to integrate the dataset with analytics platforms and internal databases.
Commercial Applications of Structured Cruise Intelligence
Cruise data distribution can support numerous commercial applications. Travel agencies can benchmark competing fares and identify attractive packages. Online travel platforms can improve search results by consolidating itinerary information. Revenue teams can monitor price movements. Market researchers can study route popularity and seasonal patterns.
Investors and analysts can use historical datasets to examine fleet deployment, capacity trends, destination concentration, and pricing behavior. Destination marketers can evaluate how frequently cruise ships visit particular ports.
Data can also support recommendation engines. By combining itinerary duration, destination preferences, cabin prices, departure ports, and sailing dates, applications can rank options according to customer requirements.
Conclusion
The U.S. cruise market generates a continuously changing stream of structured and semi-structured information. Turning this information into dependable intelligence requires a carefully designed process covering extraction, normalization, validation, historical storage, change detection, and distribution.
A successful cruise-data program should therefore be built around business objectives rather than collection volume alone. Stable ship information may need periodic refreshes, while prices and availability can require substantially more frequent monitoring. Incremental delivery can reduce operational costs, whereas API distribution can provide applications with timely access to normalized information.
When supported by appropriate source permissions, quality controls, scalable infrastructure, and well-defined schemas, cruise data intelligence can become a powerful foundation for pricing analysis, competitive benchmarking, route research, travel applications, and forecasting.
Finally, combining U.S. cruise observations with a broader Global Cruise Route Dataset can extend market intelligence beyond domestic sailings, enabling organizations to compare routes, destinations, pricing patterns, and fleet movements across international cruise markets.
Ready to elevate your travel business with cutting-edge data insights? Scrape Aggregated Flight Fares to identify competitive rates and optimize your revenue strategies efficiently. Discover emerging opportunities with tools to Extract Travel Website Data, leveraging comprehensive data to forecast market shifts and enhance your service offerings. Real-Time Travel App Data Scraping Services helps stay ahead of competitors, gaining instant insights into bookings, promotions, and customer behavior across multiple platforms. Get in touch with Travel Scrape today to explore how our end-to-end data solutions can uncover new revenue streams, enhance your offerings, and strengthen your competitive edge in the travel market.
Unlock the Full Report
Enter your details to access premium pricing intelligence insights